Recent & Upcoming Talks

2025

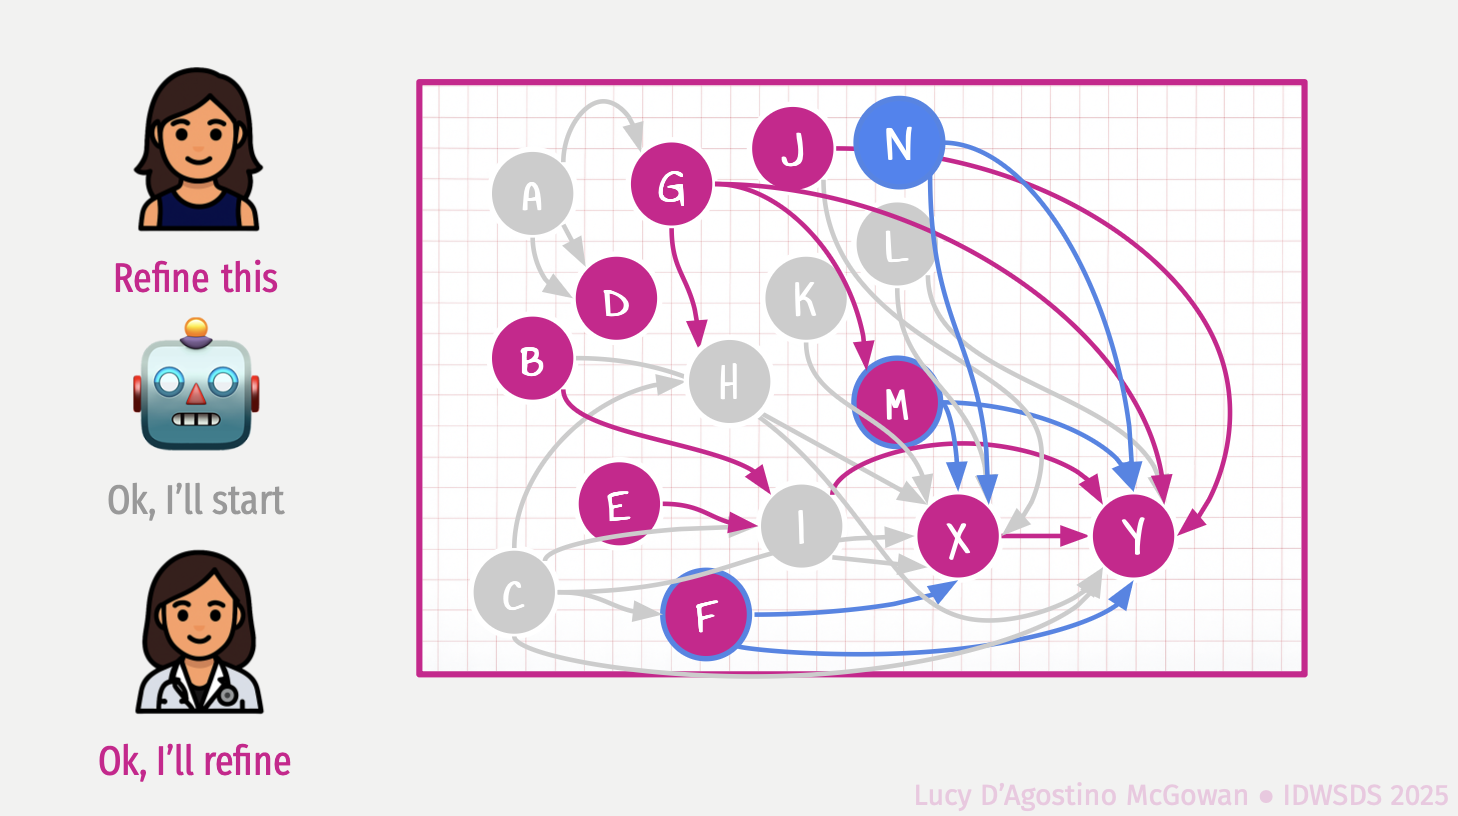
Exploring the Potential of Large Language Models in Generating Saturated DAGs for Causal Inference

This talk investigates whether large language models (LLMs) could potentially assist in the creation of “saturated DAGs”, graphical representations that exhaustively map all possible causal pathways in a system. We’ll critically examine if and how LLMs might help identify the full space of plausible causal relationships that traditional approaches may overlook. The presentation will assess the strengths and limitations of prompting LLMs to generate comprehensive causal structures, identify backdoor paths, and navigate complex causal systems.
Causal Inference Is Not Just A Statistics Problem

In this talk we will discuss four datasets, similar to Anscombe’s quartet, that aim to highlight the challenges involved when estimating causal effects. Each of the four datasets is generated based on a distinct causal mechanism: the first involves a collider, the second involves a confounder, the third involves a mediator, and the fourth involves the induction of M-Bias by an included factor. Despite the fact that the statistical summaries and visualizations for each dataset are identical, the true causal effect differs, and estimating it correctly requires knowledge of the data-generating mechanism. These example datasets can help practitioners gain a better understanding of the assumptions underlying causal inference methods and emphasize the importance of gathering more information beyond what can be obtained from statistical tools alone.

Causal Inference in R

In this workshop, we’ll teach the essential elements of answering causal questions in R through causal diagrams, and causal modeling techniques such as propensity scores and inverse probability weighting. In both data science and academic research, prediction modeling is often not enough; to answer many questions, we need to approach them causally. In this workshop, we’ll teach the essential elements of answering causal questions in R through causal diagrams, and causal modeling techniques such as propensity scores and inverse probability weighting. We’ll also show that by distinguishing predictive models from causal models, we can better take advantage of both tools. You’ll be able to use the tools you already know–the tidyverse, regression models, and more–to answer the questions that are important to your work. This workshop is for you if you: know how to fit a linear regression model in R, have a basic understanding of data manipulation and visualization using tidyverse tools, and are interested in understanding the fundamentals behind how to move from estimating correlations to causal relationships.

September 16, 2025

9:00 AM – 4:00 PM

posit::conf 2025


By Lucy D'Agostino McGowan and Malcolm Barrett in Invited Workshop

details

Immaculate vibes, questionable code

Inspired by the practical problem of chairing a useR conference session, this talk walks through building a Slido replacement in pure “vibe coding” mode — no specs, no tests, just a vision and a stubborn refusal to stop until it worked (sort of). We’ll explore the chaotic joy, the accidental brilliance, and the inevitable questionable code that got us there.

Building Strong ASA Student Chapters: Strategies for Growth, Inclusivity, and Maximizing Value

This invited panel session offers guidance for statistics and data science faculty and students seeking to establish or enhance their ASA student chapter. The panel will feature a diverse group of faculty advisors and chapter officers who will share their experiences starting and running a successful student chapter. The panelists will discuss the benefits of ASA affiliation, strategies for maintaining an active and inclusive chapter, and resources available to support students and faculty. Attendees will gain practical tips and strategies for transitioning from a statistics club to an ASA student chapter, overcoming challenges, and fostering a strong community of statistics and data science learners.

August 3, 2025

2:00 PM – 4:00 PM

ASA Joint Statistical Meeting 2025


By Lucy D'Agostino McGowan in Invited Panel

Understanding Statistics in Medical Literature

In today’s fast-paced healthcare landscape, understanding data and statistics is essential for making informed decisions. Whether you’re a medical student navigating your first journal article or a healthcare professional hoping to apply the latest research to patient care, the ability to critically evaluate medical literature is a vital skill. This course is designed to introduce you to the core concepts of data and statistics, equipping you with the tools to extract meaningful insights from research without becoming bogged down in complex mathematical notation.

July 22 – 25, 2027

10:30 AM – 3:00 PM

Statistical Horizons


By Lucy D'Agostino McGowan in Invited Workshop

details

The Case for Deterministic Imputation in Predictive Modeling

While multiple imputation is widely accepted for handling missing data in clinical research, its default use in predictive modeling may be inappropriate. Multiple imputation relies on access to the outcome variable to avoid bias, an assumption that breaks down in real-world deployment where the outcome is unknown. This talk argues that deterministic imputation methods, which do not depend on the outcome and are computationally efficient, are better suited for building predictive models intended for deployment. We present theoretical results and simulation evidence demonstrating that deterministic imputation maintains model validity and performance without introducing information leakage. We conclude that for predictive tasks, particularly in clinical settings where transparency, reproducibility, and alignment with deployment conditions are essential, deterministic imputation should be the standard.

May 13, 2025

9:00 AM – 10:00 AM

St. Jude Biostatistics and Data Science Research Forum


By Lucy D'Agostino McGowan in Invited Oral Presentation

slides

The Why Behind Including Y in your Imputation Model

Handling missing data is a frequent challenge in analyses of health data, and imputation techniques are often employed to address this issue. This talk focuses on scenarios where a covariate with missing values is to be imputed and examines the prevailing recommendation to include the outcome variable in the imputation model. Specifically, we delve into stochastic imputation methods and their effects on accurately estimating the relationship between the imputed covariate and the outcome. Through mathematical proofs and a series of simulations, we demonstrate that incorporating the outcome variable in imputation models is essential for achieving unbiased results with stochastic imputation. Furthermore, we address the concern that this practice constitutes “double dipping” or data dredging. By providing both theoretical and empirical evidence, we show why including the outcome variable is a legitimate and necessary approach rather than a source of bias.

Untangling Causal Effects: Understanding the Limits of Statistics

This talk will delve into two major causal inference obstacles: (1) identifying which variables to account for and (2) assessing the impact of unmeasured variables. The first half of the talk will showcase a Causal Quartet. In the spirit of Anscombe’s Quartet, this is a set of four datasets with identical statistical properties, yet different true causal effects due to differing data generating mechanisms. These simple datasets provide a straightforward example for statisticians to point to when explaining these concepts to collaborators and students. The second half of the talk will focus on how statistical techniques can be leveraged to examine the impact of a potential unmeasured confounder. We will examine sensitivity analyses under several scenarios with varying levels of information about potential unmeasured confounders, introducing the tipr R package, which provides tools for conducting sensitivity analyses in a flexible and accessible manner.

March 21, 2025

12:00 PM – 1:00 PM

Auburn University Department of Health Outcomes Research and Policy


By Lucy D'Agostino McGowan in Invited Oral Presentation

slides

2024

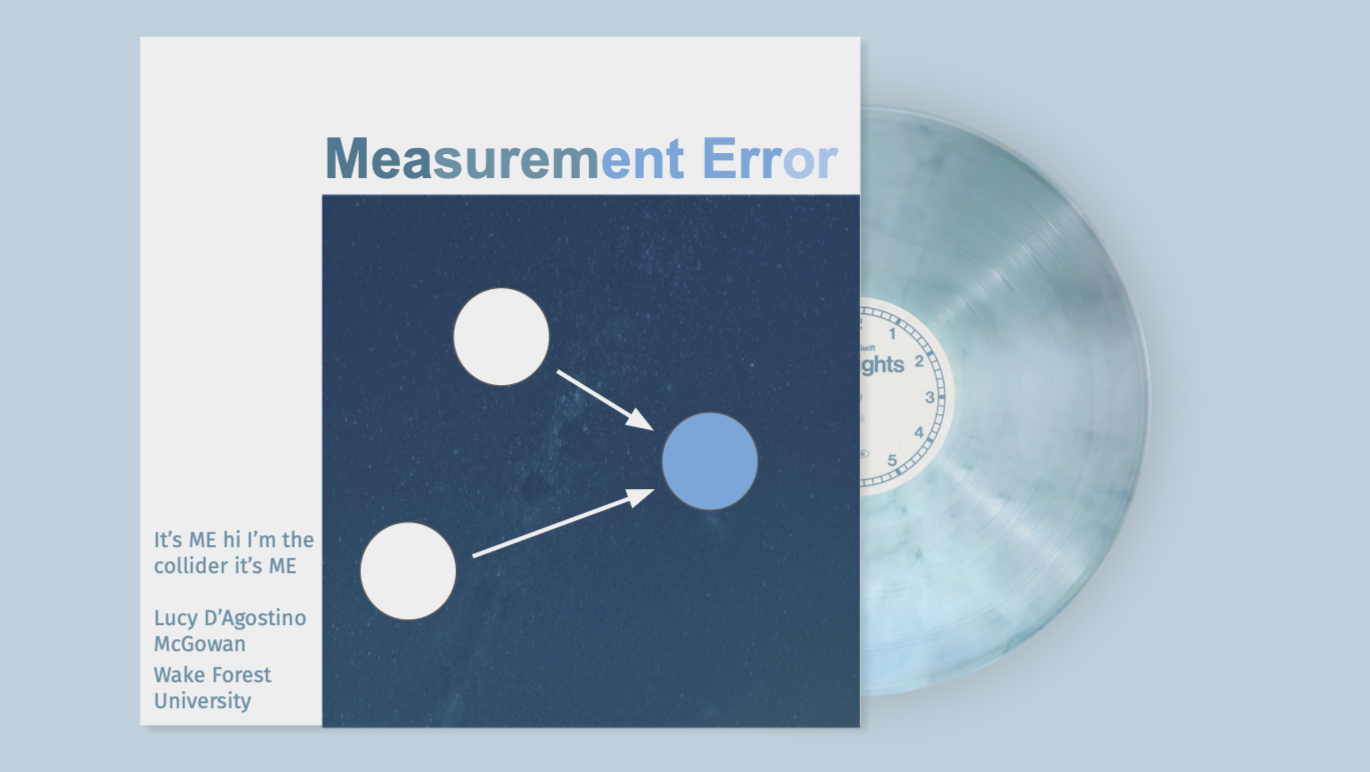
It’s ME hi, I’m the collider it’s ME

This talk will focus on framing measurement error as a collider from a causal inference perspective. We will begin by demonstrating how to visually display measurement error in directed acyclic graphs (DAGs). We will then show how these graphs can be used to help communicate when corrections for measurement error are needed and how to implement these corrections in order to estimate unbiased effects. Finally, we will demonstrate how sensitivity analyses traditionally used to address omitted variable bias can be used to quantify the potential impact of measurement error.