These days I like to discuss
- Causal Inference
- Analytic Design Theory
- Statistical Communication
- The Casual Inference Podcast
- Large-scale medical data
- Italian
- Co-founding R-Ladies Nashville
- Disney World
over coffee
Lucy D’Agostino McGowan
Lucy D’Agostino McGowan is an associate professor in the Department of Statistical Sciences at Wake Forest University. She received her PhD in Biostatistics from Vanderbilt University and completed her postdoctoral training at Johns Hopkins University Bloomberg School of Public Health. Her research focuses on causal inference, statistical communication, analytic design theory, and data science pedagogy. Dr. D’Agostino McGowan was the 2023 chair of the American Statistical Association’s Section on Statistical Graphics and can be found blogging at livefreeordichotomize.com, on Twitter @LucyStats, and podcasting on the American Journal of Epidemiology partner podcast, Casual Inference.
Recent Awards
- In 2025, Lucy received the Emerging Leader Award from the Committee of Presidents of Statistical Societies
- In 2023, Lucy was selected for the Teaching in the Health Sciences Young Investigator Award for her paper Design Principles for Data Analysis
- In 2023, Lucy was selected as an ASA StatsForward Fellow
Listen to the Casual Inference Podcast
Recent & Upcoming Talks
Miss(ing) Congeniality: Why We Care About Compatible Imputation Models
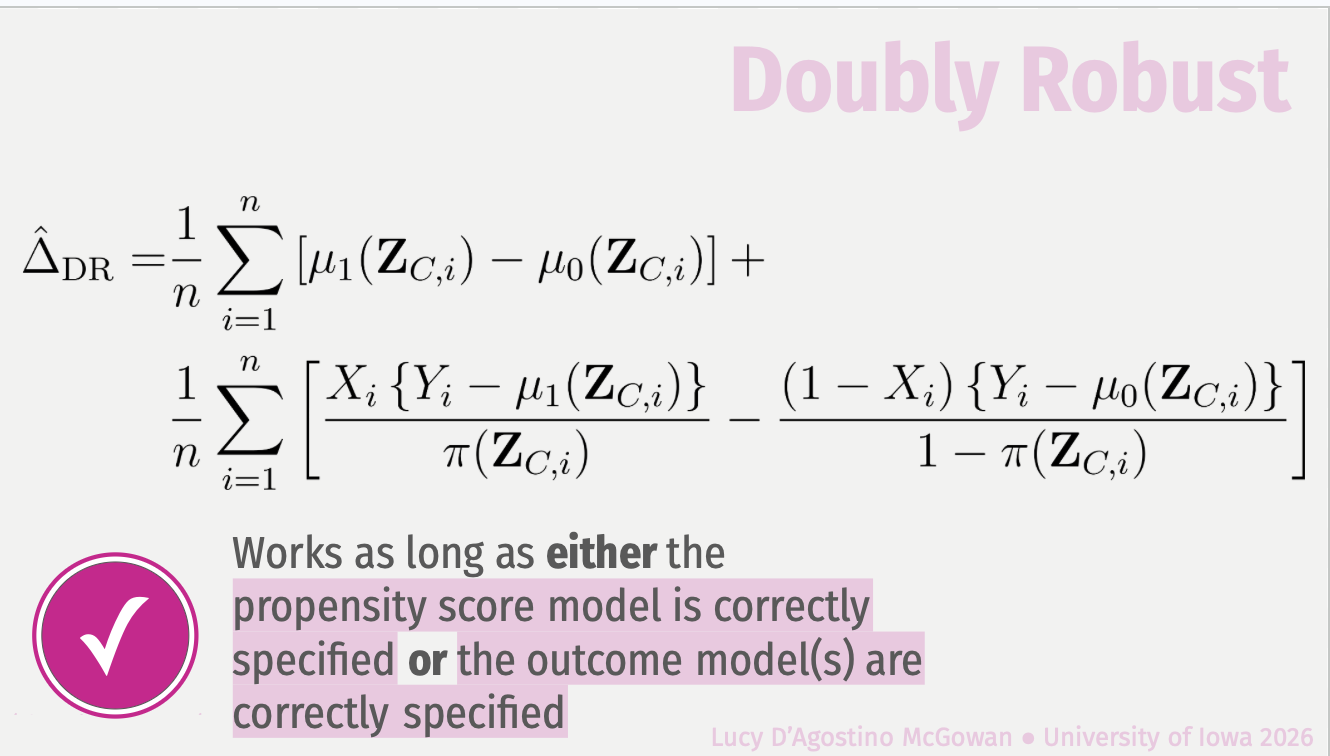
Doubly robust estimators are often viewed as protected against model misspecification, but this protection can fail in the presence of missing data. When multiple imputation is used, lack of congeniality between the imputation and analysis models can induce bias even when both the propensity score and outcome models are correctly specified. Valid inference requires imputation models to include all variables from both the propensity score and outcome models, specified in compatible functional forms. Violations of these conditions can lead to substantial bias in treatment effect estimates. A general framework for combining multiple imputation with doubly robust estimation is presented, the conditions required for congeniality are characterized, and the consequences of misspecification are illustrated. The talk concludes with practical recommendations for specifying imputation models to preserve the validity of doubly robust methods in applied causal analyses.
Read moreMissing Data Methods in Causal Inference
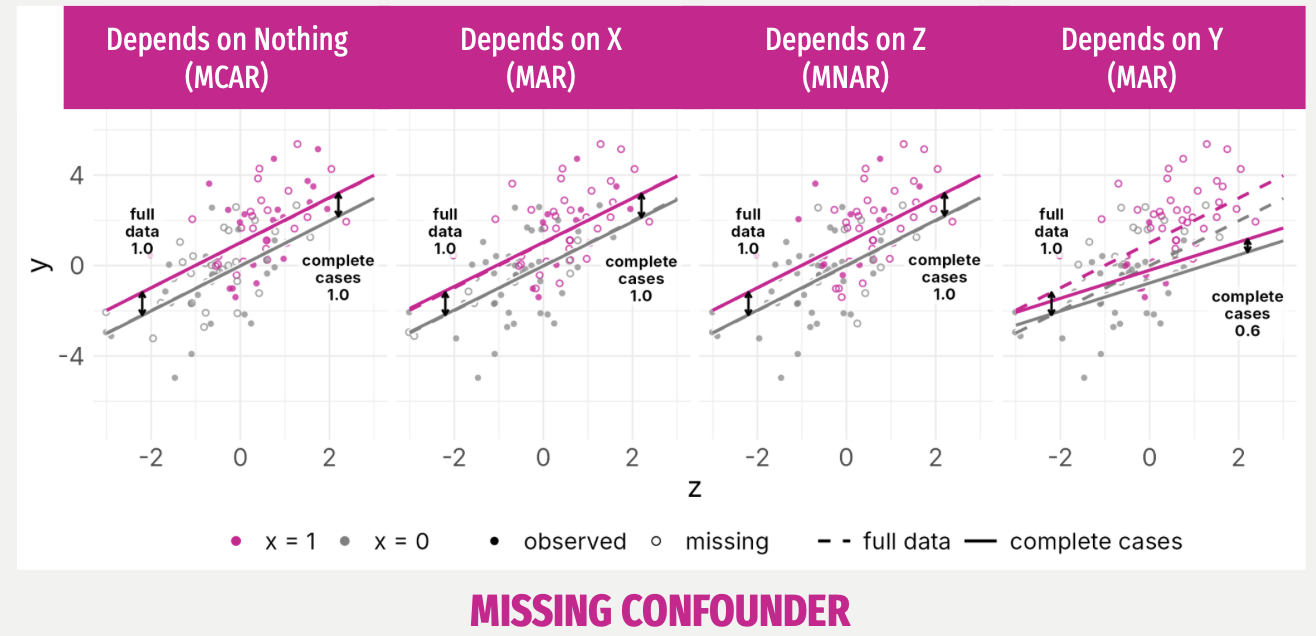
This workshop covers types of missing data seen in causal analyses and describes when dealing with them is necessary from both a bias and efficacy perspective. We then focus specfically on multiple imputation when estimating causal effects with a particular emphasis on which variables must be present in the imputation model (and in what functional form).
Read morePatients Don't Care About the Interaction Term (Should We?)
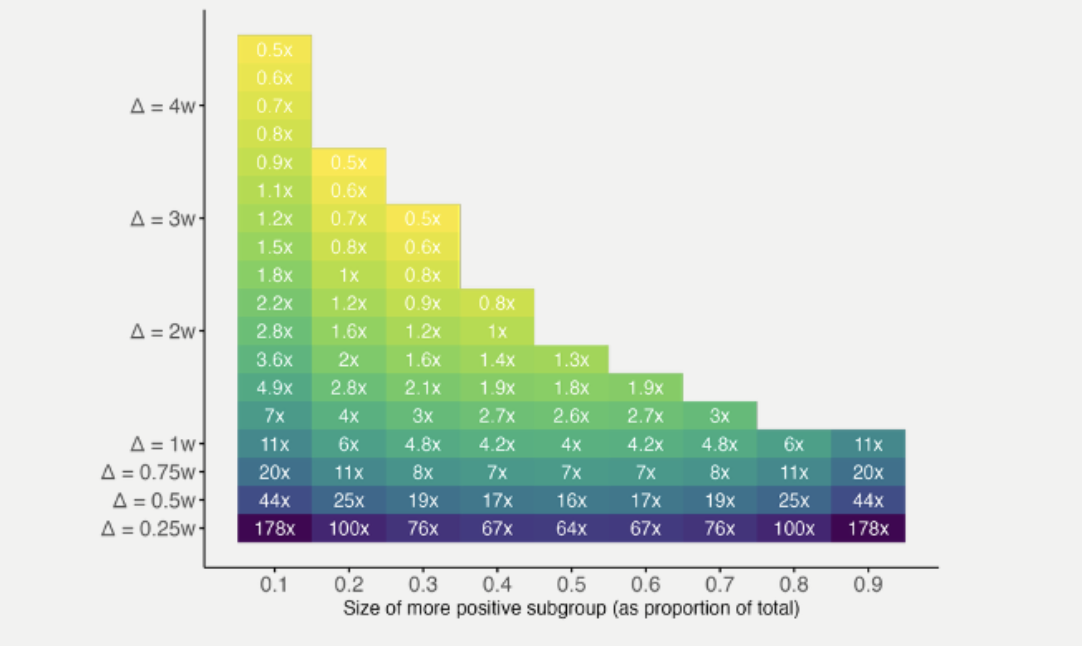
Powering a trial to detect subgroup-by-treatment interactions is, in most realistic scenarios, simply not feasible. At the design stage, investigators presume clinical equipoise, that is they do not expect treatment to harm any group of patients. The overall effect is the weighted average of subgroup-specific effects and the expectation of clinical equipoise sharply constrains how different those effects can be. Under these assumptions, the sample sizes required to detect interactions are dramatically larger than those needed to detect the overall treatment effect. In a trial designed for 80% power on the overall effect, detecting an interaction of comparable magnitude would require at least four times the sample size, and even under ideal conditions, interaction test power hovers around 29%. However, power to detect a subgroup-specific effect is not the same as power to detect an interaction, and these reflect fundamentally different scientific goals. Typically, a patient does not care whether their treatment effect is statistically distinguishable from another subgroup’s, they care whether there is a clinically and statistically meaningful benefit within their own subgroup. Meaningful, valid estimates of subgroup-specific effects are achievable without relying on formal interaction tests, and pre-specifying subgroups and reporting within-subgroup estimates directly is both statistically sound and more aligned with how patients and clinicians actually use trial results.
Read moreTeaching
STA 312 -- WFU Spring 2026
Linear models. Learn the theory behind linear models. Gain hands on experience with real data from a variety of disciplines. The course will focus on the statistical computing language R.
Read moreSTA 363 -- WFU Fall 2025
Statistical learning. Learn the theory behind cutting edge statistical and machine learning techniques. Gain hands on experience with real data from a variety of disciplines. The course will focus on the statistical computing language R.
Read moreSTA 312 -- WFU Fall 2025
Linear models. Learn the theory behind linear models. Gain hands on experience with real data from a variety of disciplines. The course will focus on the statistical computing language R.
Read moreWriting
Symmetric vaccine efficacy
Traditional measures of vaccine efficacy (VE) are inherently asymmetric, constrained above by 1 but unbounded below. As a result, VE estimates and corresponding confidence intervals (CIs) can extend far below zero, making interpretation difficult and potentially obscuring whether the apparent effect reflects true harm or simply statistical uncertainty. The proposed symmetric vaccine efficacy (SVE) is a bounded and interpretable alternative to VE that maintains desirable statistical properties while resolving these asymmetries.
Read moreUsing large language models to enhance clinically-driven missing data recovery algorithms in electronic health records
Objectives Electronic health record (EHR) data are prone to missingness and errors. Previously, we devised an enriched chart review protocol where a “roadmap” of auxiliary diagnoses was used to recover missing values. Still, chart reviews are expensive and time-intensive, limiting the number of patients whose data can be reviewed. Now, we investigate the accuracy and scalability of a roadmap-driven algorithm, based on International Classification of Diseases, 10th revision (ICD-10) codes, to mimic expert chart reviews and recover missing values.
Read morePartitioned Local Depth (PaLD) Community Analyses in R
Partitioned Local Depth (PaLD) is a framework for holistic consideration of community structure for distance-based data. This paper describes an R package, pald, for calculating Partitioned Local Depth (PaLD) probabilities, implementing community analyses, determining community clusters, and creating data visualizations to display community structure. We present essentials of the PaLD approach, describe how to use the pald package, walk through several examples, and discuss the method in relation to commonly used techniques.
Read more